Results
n = 1000 (300 bad) · labels: UCI Statlog German Credit labels (1994), recoded 2 = bad · scorer: deterministic code (scikit-learn metrics on pooled out-of-fold predictions) · model: champion-lr-sigmoid-v1 · run date: 2026-10-29 · uncertainty: percentile bootstrap, 2000 row resamples, 95% · validation: repeated stratified 5-fold CV x 5, seed 20261029
Model
| Metric (95% CI) | Champion | Challenger | Spread across repeats (champion) |
|---|---|---|---|
| AUROC | 0.780 [0.751, 0.810] | 0.792 [0.763, 0.820] | 0.771 to 0.781 |
| Expected cost per applicant | 0.541 [0.488, 0.598] | 0.537 [0.479, 0.593] | 0.538 to 0.561 |
| Brier score | 0.166 [0.155, 0.179] | 0.163 [0.152, 0.175] | 0.165 to 0.169 |
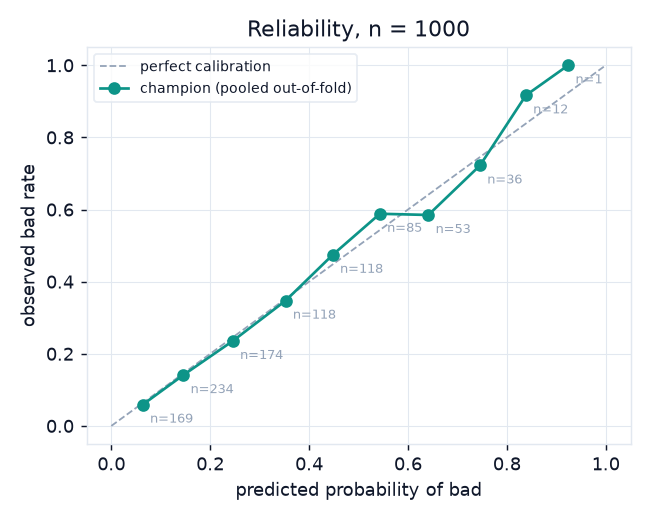
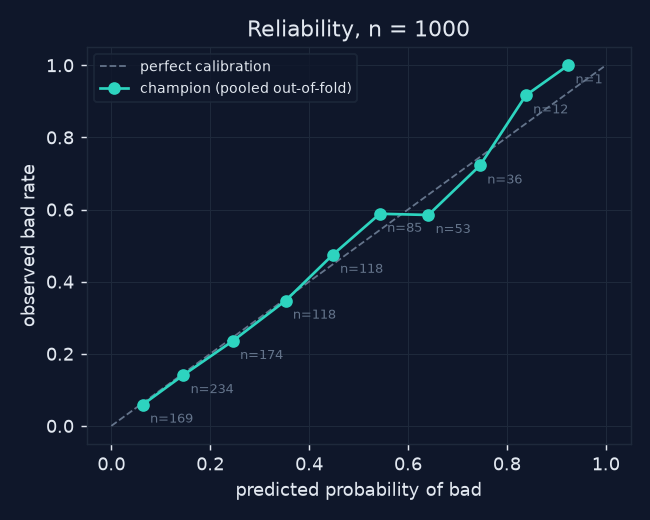
| ECE (10 bins) | 0.016 [0.018, 0.051] | 0.032 [0.025, 0.063] | 0.016 to 0.028 |
Trivial baselines: approve everyone 1.50, decline everyone 0.70 per applicant.
Challenger minus champion (paired bootstrap): AUROC 0.012 [-0.003, 0.029]; expected cost -0.004 [-0.053, 0.043].
Policy: threshold 0.1667, refer ceiling 0.25; out-of-fold band counts approve 339, refer 161, decline 500.
Serving model: fitted on n = 1000; attribution reference approve_band_training_mean (n = 340); calibration slope -0.806 (negative = monotone increasing).
Fairness (pooled out-of-fold, binary policy)
sex
Proxy audit (binary): AUROC 0.69 [0.66, 0.73].
| Group | n (bad) | Approval rate [95% CI] | Impact ratio | FPR | FNR | Calibration gap |
|---|---|---|---|---|---|---|
| female | 310 (109) | 0.326 [0.274, 0.381] | 0.94 | 0.552 | 0.101 | -0.041 |
| male | 690 (191) | 0.345 [0.309, 0.380] | 1.00 | 0.561 | 0.099 | +0.018 |
foreign worker
Proxy audit (binary): AUROC 0.75 [0.66, 0.82].
| Group | n (bad) | Approval rate [95% CI] | Impact ratio | FPR | FNR | Calibration gap |
|---|---|---|---|---|---|---|
| no | 37 (4) | insufficient n | ||||
| yes | 963 (296) | 0.335 [0.306, 0.365] | 1.00 | 0.561 | 0.101 | -0.006 |
age band
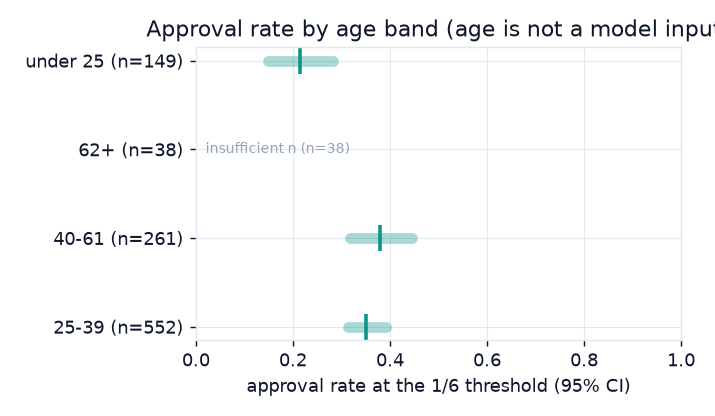
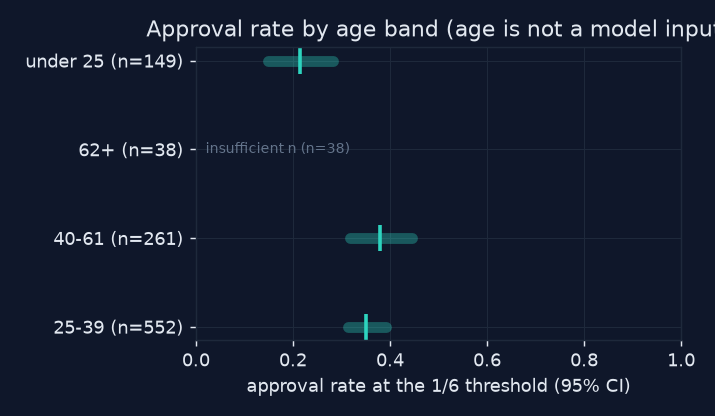
Proxy audit (macro one-vs-rest): AUROC 0.73 [0.70, 0.75].
| Group | n (bad) | Approval rate [95% CI] | Impact ratio | FPR | FNR | Calibration gap |
|---|---|---|---|---|---|---|
| 25-39 | 552 (161) | 0.351 [0.313, 0.391] | 0.93 | 0.555 | 0.124 | +0.003 |
| 40-61 | 261 (71) | 0.379 [0.318, 0.444] | 1.00 | 0.521 | 0.113 | +0.012 |
| 62+ | 38 (7) | insufficient n | ||||
| under 25 | 149 (61) | 0.215 [0.148, 0.282] | 0.57 | 0.659 | 0.033 | -0.053 |
Verifier
n = 1006 genuine notices · labels: designed by construction (mutations of genuine notices) · scorer: deterministic code · model: champion-lr-sigmoid-v1 · run date: 2026-10-30 · uncertainty: a finite test count, not an error-rate estimate
False rejects of genuine notices: 0.
| Mutator | Defect | Intended check(s) | Killed / applicable | Not applicable |
|---|---|---|---|---|
| M1 | reorder two reasons | reasons_match_derivation |
1006 / 1006 | 0 |
| M2 | drop the top reason | reasons_match_derivation |
1006 / 1006 | 0 |
| M3 | append a fifth reason | reason_count, reasons_match_derivation |
1006 / 1006 | 0 |
| M4 | prohibited-basis phrase in a reason | no_prohibited_basis |
1006 / 1006 | 0 |
| M5 | generic reason text | specific_reasons |
1006 / 1006 | 0 |
| M6 | decision statement says approved | decision_consistent |
1006 / 1006 | 0 |
| M7 | reason code not in the catalogue | reasons_match_derivation |
1006 / 1006 | 0 |
| M8 | a stated number changed | numbers_grounded |
534 / 534 | 472 |
| M9 | ECOA statement removed | legal_frame_intact |
1006 / 1006 | 0 |
| M10 | promise of approval added | approved_wording |
1006 / 1006 | 0 |
| M11 | category swapped for another value | specific_reasons |
1006 / 1006 | 0 |
| M12 | reason negated | approved_wording |
1006 / 1006 | 0 |
| M13 | zero-width character inserted | approved_wording |
1006 / 1006 | 0 |
| M14 | unapproved wording variant | approved_wording, numbers_grounded |
1006 / 1006 | 0 |
Meta-mutation: 8 of 8 checks, when disabled, made the gate fail.
Analyst guard rails
n = 19 cases · labels: designed by construction (single author) · scorer: scripted stand-in (deterministic code around a replayed model) · model: n/a (stand-in) · passed 19 / 19. This measures the code around the model, not a live model's answers.
| Case | Job | Passed |
|---|---|---|
| A1 | evidence_qa | yes |
| A2 | evidence_qa | yes |
| A3 | evidence_qa | yes |
| A4 | evidence_qa | yes |
| G1 | grounding | yes |
| G2 | grounding | yes |
| G3 | grounding | yes |
| G4 | grounding | yes |
| G5 | grounding | yes |
| G6 | grounding | yes |
| C1 | case_explainer | yes |
| D1 | data_query | yes |
| D2 | data_query | yes |
| R1 | refusal | yes |
| R2 | refusal | yes |
| R3 | refusal | yes |
| H1 | reports | yes |
| H3 | reports | yes |
| H2 | reports | yes |
Analyst live-model run (not gated)
n = 15 questions · labels: designed by construction (single author); expectations are tool calls and refusals, not answer quality · scorer: deterministic code checks on tool calls and refusals, plus the analyst's own grounding check; no human or LLM judge of answer quality · model: gpt-4o-mini · run date: 2026-10-30 · uncertainty: n = 15 is too small for a confidence interval; read these as a smoke test of one model, not a rate
Behaved as expected (right tools, refusals, approval held): 15 / 15. Of 12 answers containing numbers: 10 verified first try, 1 after one repair, 1 flagged unverified. Median 4.8 s per question.
For comparison, the first live run before the fixes described in the case study: behaved as expected 8 / 15; of 5 answers with numbers, 1 verified first try and 4 flagged; median 7.4 s.
| Case | Job | Tools called | Grounded | Repairs | Behaved |
|---|---|---|---|---|---|
| E1 | evidence_qa | get_evidence | yes | 0 | yes |
| E2 | evidence_qa | get_evidence | yes | 1 | yes |
| E3 | evidence_qa | get_evidence | yes | 0 | yes |
| E4 | evidence_qa | get_fairness_table, query_benchmark | yes | 0 | yes |
| E5 | evidence_qa | query_benchmark, get_fairness_table | yes | 0 | yes |
| D1 | data_query | query_benchmark | yes | 0 | yes |
| D2 | data_query | query_benchmark | yes | 0 | yes |
| D3 | data_query | query_benchmark, get_fairness_table | yes | 0 | yes |
| Q1 | queue | get_queue_summary | yes | 0 | yes |
| C1 | case_explainer | get_case, get_evidence, get_fairness_table | yes | 0 | yes |
| C2 | case_explainer | get_case | yes | 0 | yes |
| R1 | refusal | none | yes | 0 | yes |
| R2 | refusal | none | yes | 0 | yes |
| R3 | refusal | none | yes | 0 | yes |
| P1 | reports | get_evidence, get_fairness_table, save_report_draft | flagged | 1 | yes |