DualLens Analytics
Company analysis through two lenses: the financials, and what the company says about AI.
An investment-research prototype that pairs Yahoo Finance metrics with AI-strategy insights retrieved from company reports through RAG. Every answer is scored for groundedness and relevance by an LLM judge, and companies can be compared and ranked on both lenses.
- automated tests
- 36+
- analysis views
- 4
- groundedness & relevance score on every answer
- 1–5
Why it exists
Analysts increasingly need to judge two very different things about a company at once: its financial health, which lives in structured market data, and its AI strategy, which lives in long, unstructured reports. The first is easy to chart. The second usually means reading dozens of pages per company — and LLM summaries of those pages are only useful if you can tell when they are grounded in the source.
DualLens puts both lenses in one place and makes the quality of every generated answer visible.
How it works
- 01 Input Company reports (PDF)
- 02 Code Chunk & embed 1,000-token chunks, 200 overlap
- 03 Model / AI Retrieve & answer top-k from ChromaDB
- 04 Check LLM-as-judge groundedness & relevance, 1–5
- 05 Code Market metrics Yahoo Finance
- 06 Output Compare & rank
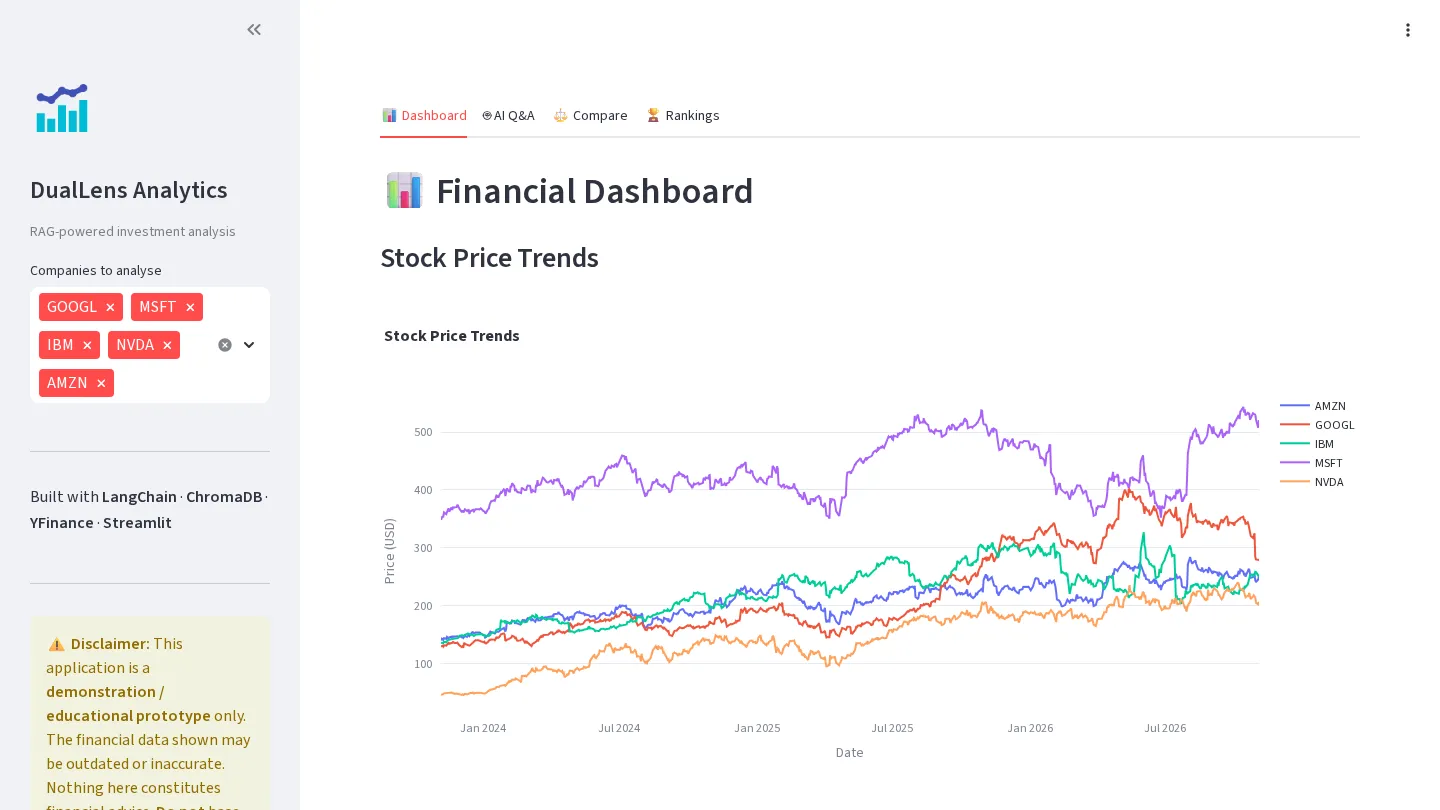
- Quantitative lens: stock prices and key financial metrics come straight from Yahoo Finance and are charted with Plotly — no model involved.
- Qualitative lens: company AI-initiative reports are parsed, split into overlapping token-based chunks and embedded into ChromaDB. Questions are answered from the most relevant chunks.
- Every answer is judged. A separate LLM-as-judge step scores each response for groundedness and relevance on a 1–5 scale, with a written justification shown next to the answer.
- Four views: a financial dashboard, a chat-style Q&A over the reports, a side-by-side company comparison, and a composite ranking that blends financial health with an LLM-assessed AI-strategy score, each with its justification.
Results and honest limits
- Delivery: a live Streamlit app with four analysis views, a documentation site, and a configurable company list (by default GOOGL, MSFT, IBM, NVDA and AMZN).
- Quality gates: 36+ automated tests covering configuration, data processing, evaluation logic and financial calculations, plus lint and format checks in a single
make check. - Configuration: chunking, retrieval depth, models and companies are set in Hydra config rather than in code.
Engineering decisions
- Keep the numbers out of the LLM. Financial metrics are fetched and computed in code; the model only works with the unstructured reports.
- Evaluate every response, visibly. Groundedness and relevance are surfaced to the user instead of being hidden in logs.
- Token-aware chunking with overlap, so retrieval does not cut context at arbitrary character boundaries.
- Externalized configuration with Hydra, so experiments with chunking and retrieval are reproducible config changes.
Who it’s for
For research and strategy teams, it is a pattern for combining structured data with retrieval over documents while keeping answer quality visible. For AI teams, it shows a lightweight way to put LLM-as-judge evaluation in front of users rather than only in offline tests.